Technical SEO Audit Checklist: 15 Essential Checks
Updated: Sep 24
A technical SEO audit can produce hundreds of warnings, but not every warning prevents growth. This practical technical SEO audit checklist helps you review the areas that affect crawling, indexing and user experience—and organize the findings into a sensible order instead of treating every issue as equally urgent.

Technical SEO Audit Checklist at a Glance
A technical SEO audit should verify whether search engines can crawl, render, understand and index the right pages. Start with access and indexing blockers, then review canonicals, redirects, internal linking, mobile parity, Core Web Vitals, JavaScript rendering, structured data and international targeting. Prioritize every finding by affected pages, likely impact and implementation effort.
The essential checks are:
preferred domain, HTTPS and redirect consistency;
robots.txt, XML sitemaps and index-control directives;
canonical tags, duplicate URLs and HTTP status codes;
internal linking, orphan pages and site architecture;
mobile content parity and Core Web Vitals;
JavaScript rendering and structured-data validity;
hreflang implementation for international websites;
clear priorities, affected-page examples and responsible owners.
What Is a Technical SEO Audit Checklist?
A technical SEO audit checklist is a structured way to examine whether search engines can access, render, understand and index the right pages on a website. It also covers technical factors that affect users, including mobile usability, security and page performance.
The checklist is only the starting point. A crawler can identify patterns and errors, but it cannot automatically determine which pages generate leads, which templates are strategically important or which problem is causing the greatest business impact. That requires context and manual review.
This SEO technical audit checklist therefore focuses on two questions:
Is the issue preventing important content from being discovered, rendered or indexed?
If not, how much traffic, revenue or implementation risk could the issue affect?
Before You Start the Audit
Collect a basic evidence set before changing anything:
access to Google Search Console;
analytics data, if available;
a complete crawl of the public website;
the current XML sitemap and robots.txt file;
a list of priority products, services, categories or landing pages;
notes about recent migrations, redesigns, CMS changes or traffic drops.
Save the date and settings used for the crawl. If the site changes during the review, two crawls made with different settings can create misleading comparisons.
Use three practical priority levels throughout the audit:
Critical: Important content cannot be reached, rendered or indexed, or users encounter a serious failure.
High: The issue affects an important template, a large group of pages or a commercially valuable section.
Medium: The issue creates inefficiency, inconsistency or a smaller opportunity but does not block the site’s essential search visibility.

Technical SEO Audit Checklist
1. Confirm the Preferred Domain and HTTPS Version
Priority: Critical if multiple versions remain accessible without consolidation.
Check whether the site resolves consistently to one preferred version, for example:
https://example.com/
https://www.example.com/
http://example.com/
http://www.example.com/
The non-preferred versions should redirect cleanly to the preferred HTTPS version. Also look for mixed-content warnings, expired certificates and internal links that still point to HTTP URLs.
Record: affected host or protocol versions, redirect destination and responsible owner.
2. Review robots.txt Access Rules
Priority: Critical when an important section or required resource is blocked.
Open the robots.txt file and review every Disallow rule. Pay particular attention to product, service, category, blog and JavaScript or CSS paths.
Remember that robots.txt controls crawling, not reliable removal from Google’s index. Google explicitly advises using noindex or access protection when a page must be kept out of Search. See Google’s robots.txt guidance.
Record: the blocked path, whether the block is intentional and the change required.
3. Validate the XML Sitemap
Priority: High, or Critical when the sitemap omits an essential section after a launch or migration.
An XML sitemap should help search engines find the URLs you want indexed. Review it for:
important URLs that are missing;
redirected, broken or server-error URLs;
non-canonical URLs;
pages marked noindex;
duplicate URL formats;
outdated URLs from an earlier site structure.
Submitting a sitemap helps with discovery, but it does not guarantee crawling or indexing. Google explains this distinction in its sitemap documentation.
Record: sitemap URL, submitted status, processing errors and mismatches with the indexable crawl.
4. Compare Important Pages With Google’s Indexing Data
Priority: Critical when strategic pages are not indexed.
Use the Page indexing report and URL Inspection in Google Search Console to compare your intended indexable pages with the URLs Google has actually processed. Investigate patterns such as:
excluded priority pages;
“Crawled — currently not indexed” URLs;
“Discovered — currently not indexed” URLs;
duplicate pages with an unexpected canonical;
soft 404s;
blocked or inaccessible pages.
Do not judge index health by the total indexed-page count alone. A smaller index containing the right pages can be healthier than a larger index filled with duplicates, filters and low-value URLs.
Record: affected page type, number of URLs, examples and whether the pattern is intentional.
5. Audit noindex and X-Robots-Tag Directives
Priority: Critical when an important page is excluded accidentally.
Check index-control directives in both the HTML and HTTP headers. A page blocked in robots.txt may prevent Google from seeing its noindex directive, so do not use these controls interchangeably. Google’s noindex documentation explains that the page must remain crawlable for the directive to be detected.
Review template-level settings carefully. A single CMS change can apply noindex to an entire category, product type or language version.
Record: directive source, affected template and whether the exclusion is intended.
6. Align Canonical Signals
Priority: High, or Critical when Google selects the wrong version of a commercially important page.
Check that canonical tags point to the preferred, live and indexable version of each page. Compare canonicals with:
internal links;
XML sitemap URLs;
redirects;
hreflang annotations;
HTTP and HTTPS versions;
parameter and faceted-navigation URLs.
Canonical tags are signals, not a guarantee that Google will select the nominated URL. Conflicting signals make consolidation less predictable. Review Google’s canonicalization guidance when investigating mismatches.
Record: declared canonical, Google-selected canonical, conflict and preferred resolution.
7. Check HTTP Status Codes and Redirects
Priority: Critical for server errors or broken priority journeys; High for large redirect patterns.
Review internal URLs returning:
3xx redirects;
4xx client errors;
5xx server errors;
soft 404 responses;
200 responses with empty or failed content.
Update internal links so they point directly to the final destination instead of passing through redirect chains. When a URL has moved permanently, Google recommends a permanent server-side redirect such as 301 or 308; temporary moves require a temporary redirect. See Google’s redirect guidance.
Record: source URL, status, final destination, number of hops and affected traffic path.
8. Find Broken Internal Links and Orphan Pages
Priority: High when important content is isolated or linked through broken URLs.
Identify internal links leading to errors, redirected destinations or URLs that cannot be crawled. Then compare crawler data, sitemaps, analytics and Search Console to find important pages with no crawlable internal links.
An XML sitemap is not a substitute for a useful internal-link structure. Priority pages should be reachable through normal navigation or contextual links, using crawlable links and descriptive anchor text.
Record: orphan or broken destination, referring pages and the most relevant place to add or repair a link.
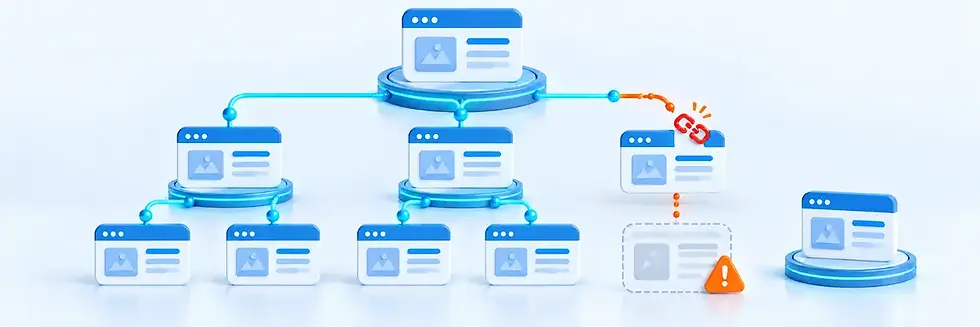
9. Review Site Architecture and Click Depth
Priority: High when important pages sit deep in the site or authority flows toward low-value URLs.
Review how homepage, navigation, category, service, product and article pages connect. Look for:
strategic pages several levels away from primary navigation;
dead-end pages;
oversized category structures;
inconsistent breadcrumbs;
important pages linked only from the footer;
repeated links to low-value utility pages.
The goal is not to force every URL within an arbitrary number of clicks. The goal is to make business importance visible through a logical hierarchy and useful internal links.
Record: page group, current depth, intended parent and proposed internal-link source.
10. Control Duplicate and Parameter URLs
Priority: High when duplicates consume substantial crawling or compete with preferred pages.
Check URL parameters, filters, sorting options, tracking codes, print versions, trailing-slash variants and uppercase or lowercase variations. Determine whether each variation should:
remain indexable as a genuinely useful page;
consolidate through a canonical;
redirect to one preferred URL;
stay crawlable but carry noindex;
be prevented from being generated or linked internally.
Do not apply one blanket solution to every parameter. Ecommerce filters, campaign tracking and internal search URLs can require different treatment.
Record: URL pattern, scale, current signals, intended search role and proposed control.
11. Check Mobile Content and Technical Parity
Priority: Critical when important mobile content, links or metadata are missing.
Google predominantly evaluates the mobile version of a site for indexing. Compare mobile and desktop versions for:
primary content;
title and description metadata;
structured data;
canonical and robots directives;
internal links;
image alt text;
status codes and redirects.
Responsive design is generally the simplest configuration to maintain, but it still needs testing across actual screen sizes. Google’s mobile-first indexing guidance explains the required parity.
Record: missing or changed mobile element, affected template and business impact.
12. Evaluate Core Web Vitals and Page Performance
Priority: High when important templates provide a consistently poor user experience.
Use field data when available and lab testing for diagnosis. The current “good” Core Web Vitals thresholds are:
LCP: 2.5 seconds or less;
INP: 200 milliseconds or less;
CLS: 0.1 or less.
These thresholds are assessed at the 75th percentile. Test representative page templates rather than one convenient URL. Typical causes include late-loading hero images, excessive JavaScript, slow server response, third-party scripts and elements without reserved dimensions. See the official Web Vitals thresholds.
Core Web Vitals contribute to page experience, but passing them does not guarantee high rankings. Content relevance and many other signals still matter.
Record: template, metric, field and lab result, likely cause and technical owner.

13. Verify JavaScript Rendering
Priority: Critical when essential content or links are absent from the rendered page.
For JavaScript-heavy websites, compare the initial HTML, rendered HTML and what Google sees through URL Inspection. Confirm that important content, canonical tags, robots directives, structured data and internal links are available after rendering.
Blocked scripts, failed API calls, client-side errors or delayed rendering can prevent search engines from receiving the same useful page that users see. Google describes the crawl-render-index sequence in its JavaScript SEO guidance.
Record: missing rendered element, affected browser or template, reproduction steps and developer owner.
14. Validate Structured Data
Priority: High for invalid markup on eligible priority pages; Medium for enhancement opportunities.
Validate structured data with the Rich Results Test and compare the markup with visible page content. Check for:
missing required properties;
invalid values;
markup describing content that users cannot see;
the wrong schema type;
inconsistent entity details across templates;
markup that disappears during JavaScript rendering.
Valid structured data can make a page eligible for a richer search appearance, but it does not guarantee that Google will show one. Follow Google’s structured-data guidelines.
Record: page type, schema type, error or warning, affected URLs and owner.
15. Check hreflang on International Sites
Priority: High when search engines show the wrong language or regional URL.
If the website has localized versions, confirm that every relevant page:
uses a separate, crawlable URL;
identifies the correct language or language-region code;
references itself and the equivalent alternatives;
receives reciprocal annotations from those alternatives;
points users and search engines to a genuinely equivalent page;
uses canonical signals that are consistent with the localized structure.
Missing return links, invalid codes and links to redirected URLs are common causes of broken clusters. Google recommends separate URLs for language versions and explains the implementation in its hreflang documentation.
Record: language cluster, missing or conflicting annotation and intended equivalent page.
How to Perform a Technical SEO Audit in the Right Order
The number of detected issues is not the same as their importance. Use this order when turning the checklist into work:
Remove access and indexing blockers. Start with server failures, accidental blocks, incorrect noindex directives and major canonical errors affecting priority pages.
Repair important journeys and templates. Fix broken links, redirect problems, rendering failures and mobile inconsistencies across commercially important areas.
Reduce large-scale duplication and crawl waste. Address parameters, faceted navigation and recurring template problems based on their scale.
Improve performance and search enhancements. Prioritize Core Web Vitals and structured-data work where users and organic visibility are most affected.
Handle smaller cleanup items. Finish isolated inconsistencies after higher-impact work has clear owners.
For every recommendation, document:
the issue;
why it matters;
affected page examples;
estimated scale;
priority;
suggested owner;
a clear next action.
That turns a crawler export into an implementation plan.
What an Automated Checklist Cannot Decide
Automated audit tools are valuable for collecting evidence at scale, but their severity labels are generic. A warning on a low-value archive page may matter less than a subtle indexing problem on one key service page.
Manual review is needed to answer questions such as:
Which pages support revenue or lead generation?
Is a technical pattern intentional for this CMS?
Does Google agree with the site’s preferred canonical structure?
Is the same issue repeated across a template?
Which fix depends on development, content or SEO ownership?
Could the proposed fix create a new indexing or user-experience problem?
This is why a useful audit report should explain priorities and ownership, not simply list errors.
How Often Should You Run a Technical SEO Audit?
The right schedule depends on how often the site changes. Run a focused technical review:
before and after a migration, redesign or domain change;
after major CMS, navigation or template updates;
when an important section is launched;
after an unexplained organic traffic or indexing change;
regularly for large ecommerce, publishing or marketplace sites.
A smaller, stable website may need fewer comprehensive reviews, but Search Console monitoring should continue between audits. Recheck implemented fixes instead of assuming that closing a task means the issue is resolved.
Technical SEO Audit Checklist: Final Takeaway
A strong technical audit does three things: it finds problems, connects them to important pages and puts the fixes in the right order. Start with crawling and indexing blockers, then address site-wide patterns, performance and enhancements according to business impact.
If you want the site reviewed manually and the findings turned into an implementation-ready plan, see our Technical SEO Audit services. To start with a smaller review, use the free manual mini audit.


